NafiulData

Data engineering studio in Central Java, Indonesia. Remote-first, working in UTC+7.

Pipelines that run on schedule, recover on their own, and raise a flag when they can’t.

We design and build the data systems behind your numbers: lakehouses, warehouses, streaming jobs and the APIs that serve them. Every pipeline we ship is safe to rerun, quarantines bad rows with a reason, and tells someone when it needs help.

nafiul-data / daily run running
  1. mobility_lakehouse.silversuccessbad fares quarantined with reason
  2. mobility_lakehouse.goldsuccessmonth overwritten, safe to rerun
  3. mobility_lakehouse.streamretry 1/2late events merged, no alert needed
  4. esim_usage.dbt_buildsuccess20 countries, duplicates removed
  5. spasi.ai_gradingquarantined1 malformed answer sent to DLQ
  6. spasi.sheets_syncsuccessgrades written per class
  7. pipeline_lint.ci_gateblockedDE003 stopped a bad merge
ran clean recovered or flagged stopped on purpose
  • Ride-hailing analyticsCommercial client, under NDA
  • eSIM travel connectivityCommercial client, under NDA
  • Secondary school, ~120 students5-year renewable contract
  • Fish procurement business~1 ton of catch a week

Selected work

Five systems in production or delivered to clients, two case studies, plus what we are building next. Client names are withheld where an NDA applies.

Client
Commercial client, under NDA
Year
2026
Release
v1.0.0, open source

Mobility Lakehouse

A batch and streaming lakehouse for ride-hailing trip data, delivered to a commercial client under NDA. The public open source version is built on the NYC TLC high-volume for-hire dataset from 2024 onward.

  • Bronze, silver and gold layers in PySpark and Delta Lake on Databricks. Each month is overwritten as a unit, so any rerun gives the same result.
  • Quality rules written from profiling real months: negative fares or driver pay go to a quarantine table with the reason attached; pickups logged before the request are kept and counted as warnings.
  • A streaming path with Redpanda and Spark Structured Streaming that handles late-arriving events, and a FastAPI service that serves the gold layer.
  • Thirteen architecture decision records explain every trade-off for the next engineer.
  • Databricks
  • PySpark
  • Delta Lake
  • Redpanda
  • Spark Streaming
  • FastAPI
  • Python 3.12
  • uv
Client
Secondary school, ~120 students
Year
2026, ongoing
Contract
5 years, renewable

SPASI, AI-graded homework platform

Students upload homework from their phones; an AI grades it against the teacher’s rubric; grades land in each class’s Google Sheet where teachers can override them.

  • Event-driven flow, FastAPI to Redis to stateless Python workers, with idempotent PostgreSQL upserts so a resubmission never creates a duplicate.
  • Gemini grading is held to a fixed JSON schema. Malformed or hallucinated answers go to a dead letter queue and trigger an alert.
  • School policy as code: geofencing flags homework sent from inside the school grounds, and late uploads are accepted with an automatic 20% penalty instead of being rejected.
  • Privacy for minors: identities hashed to UUIDs with a secret pepper, phone numbers encrypted, raw GPS deleted within 24 hours. Terraform on GCP, tests in GitHub Actions.
  • FastAPI
  • Redis
  • PostgreSQL
  • Gemini API
  • Google Sheets API
  • Terraform
  • GCP
  • GitHub Actions
Type
Open source product
Year
2026
Release
v0.1.0 on PyPI

pipeline-lint

A linter for SQL, PySpark, Databricks and Airflow code that catches the mistakes AI-written pipelines make, before they reach production.

  • Seven rules, DE001 to DE007, aimed at failures that silently corrupt warehouse tables when a scheduler retries a job: non-idempotent writes, duplicate data on rerun and more.
  • A CLI that fails CI on violations, with --fail-on error so each team decides how strict the merge gate is.
  • Released through GitHub Actions with Trusted Publishing, so no long-lived API tokens are stored. Next: an incremental-watermark rule and a VS Code extension.
  • Python
  • SQL
  • PySpark
  • Airflow
  • GitHub Actions
  • PyPI
  • Apache-2.0
pip install pipeline-lint
Client
eSIM travel connectivity, under NDA
Year
2026
Scope
ELT, warehouse, API

Global telecom usage pipeline

An ELT pipeline that turns raw eSIM usage from 20 countries into an analysis-ready BigQuery warehouse, with an API for internal services.

  • Four core entities, destinations, plans, customers and sessions, modelled in dbt across 90 days of session history for 2,000+ users.
  • Automated validation, connection status checks and deduplication across source tables.
  • A FastAPI service exposes connectivity data and usage insights to other teams.
  • Python
  • SQL
  • dbt
  • BigQuery
  • FastAPI
  • GCP
Type
Case study
Year
2026
Schedule
Daily

Manufacturing ELT warehouse (case study)

A case study design for a metalworking plant: a daily ELT pipeline that brings four operational areas into one analytical warehouse the whole plant can query.

  • Airflow orchestrates extraction into PostgreSQL and dbt transformations into analysis-ready models.
  • Every run retries twice on its own, times out any task after 30 minutes, and sends a Telegram alert only when it truly fails.
  • Stress-tested with a synthetic dataset in which about 2.5% of records were deliberately dirty.
  • Airflow
  • PostgreSQL
  • dbt
  • Python
  • Telegram alerts
Client
Fish procurement business
Year
2026, ongoing
Volume
~1 ton of fish a week

Fishery bookkeeping app

An offline-first Android app that replaced paper ledgers for a business buying catch from 100 to 200 GT vessels, about Rp50 million in transactions every week.

  • Transaction data modelled around vessel, catch category, weight and price per kg, with price categories and margins calculated the moment a record is entered.
  • Local-first storage with HiveDB, so operators can record purchases at the harbour with no signal.
  • Excel ledger export and PDF receipts for thermal printers replace hand-written books.
  • Flutter
  • Dart
  • HiveDB
  • Excel export
  • PDF

Every project at a glance

ProjectForStackStatus
Mobility LakehouseRide-hailing client, NDADatabricks, PySpark, Delta Lake, Redpanda, FastAPIDelivered
SPASI homework platformSecondary schoolFastAPI, Redis, PostgreSQL, Gemini, Terraform, GCPIn production
pipeline-lintOpen sourcePython, SQL, PySpark, Airflow, GitHub Actionsv0.1.0 on PyPI
Global telecom usage pipelineeSIM client, NDAdbt, BigQuery, FastAPI, PythonDelivered
Manufacturing ELT warehouseCase study, metalworkingAirflow, PostgreSQL, dbt, TelegramCase study
Fishery bookkeeping appFish procurement businessFlutter, Dart, HiveDBIn production
Sales data pipeline automationCase study, retail salesPython, SQL, GitCase study
IDX signal engineInternal researchPython, React Native, ElectronIn development
Data engineering simulatorOpen source learningDatabricks, Power BI, SAPIn design

The sales pipeline case study extracts and cleans recurring sales records into a SQL database and generates summary reports automatically, replacing manual end-of-day summaries.

In the lab

Things we are building for ourselves first.

In development

IDX signal engine

A monthly ranking engine for Indonesian equities. It picks the ten strongest stocks each month, holds cash when the index trades below its 50-day average, and is backtested on 2021 to 2026 data. It sends signals only; trades are placed by hand. Desktop and mobile apps are built with Electron and React Native.

Internal research, not investment advice.

In design

Data engineering simulator

A hands-on course that takes learners from level 0 to level 10, with a from-scratch mode for beginners and a scaffolded mode for those who want a challenge. Covers Databricks, Power BI and SAP.

What we build

Four kinds of work, usually combined in one engagement.

Pipelines and orchestration
Batch ELT and streaming jobs in Airflow, Spark and Redpanda. Retries, timeouts and alerts are part of the first version, not a later ticket.
Airflow, PySpark, Redpanda, Python
Lakehouses and warehouses
Bronze, silver and gold layers on Databricks, or dbt models on BigQuery and PostgreSQL, documented so your analysts can trust every column.
Databricks, Delta Lake, dbt, BigQuery, PostgreSQL
Data quality and reliability
Rules written from profiling your real data. Bad rows are quarantined with a reason instead of dropped, and every write is safe to rerun.
pipeline-lint, dbt tests, idempotent upserts
APIs, AI and operations tools
FastAPI services on top of your warehouse, LLM steps held to a strict schema, and offline-first apps or Google Sheets syncs for teams who live outside the database.
FastAPI, Gemini, Flutter, Google Sheets API, Terraform

How we work

Remote by default from UTC+7, which overlaps the European morning and the US evening.

  1. Profile the data you already have

    We read your real tables and files before writing a rule. Quality checks come from what the data actually does, not what the schema promises.

  2. Write the decisions down

    Each architecture choice gets a short decision record: what we chose, what we rejected and why. You keep these after we leave.

  3. Build it to survive a rerun

    Idempotent writes, quarantine tables, retries and alerts, with tests in CI and infrastructure as code where the project needs it.

  4. Hand it over in a state you can run

    Your team gets the repository, the runbook and a walkthrough. Contracts can continue with maintenance, like our five-year school engagement.

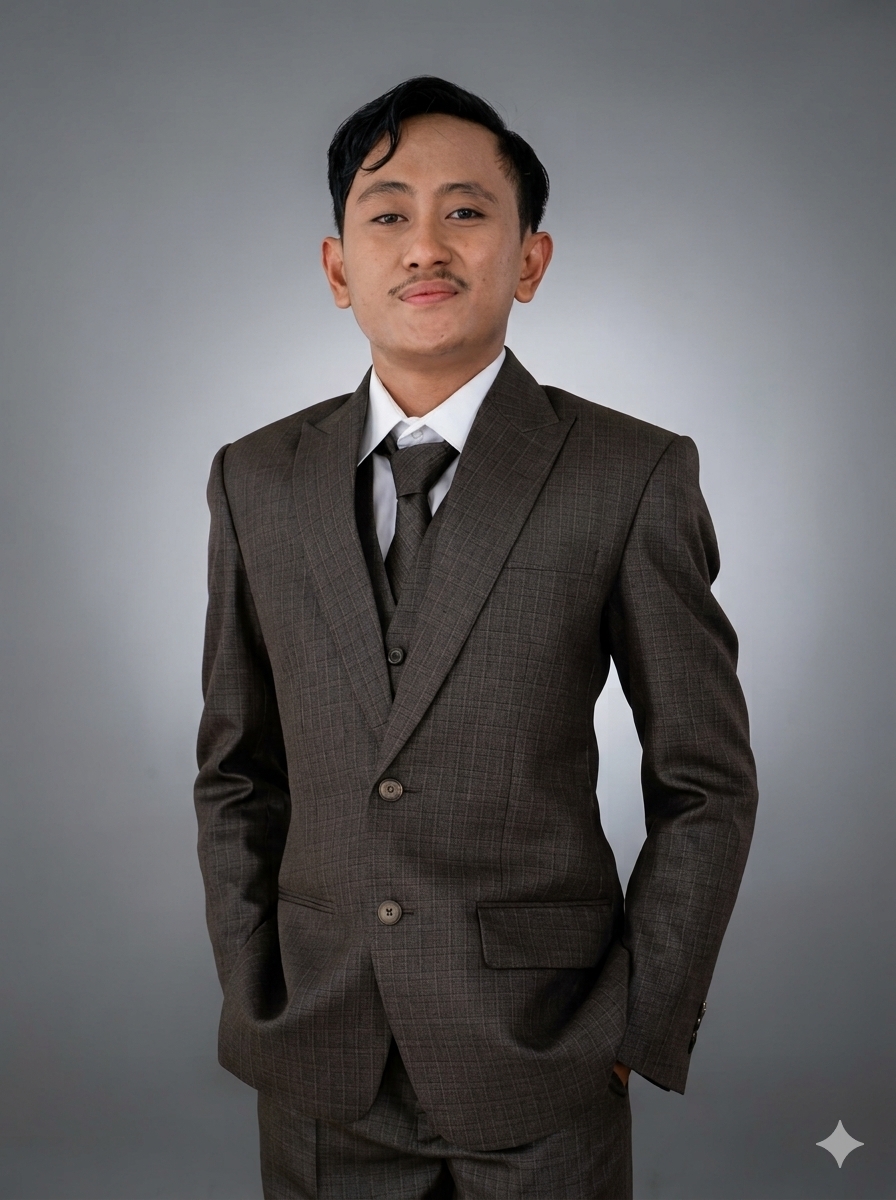
Nafiul Hadi Saputra

Founded by Nafiul Hadi Saputra

Nafiul has spent more than five years in public-sector data operations at the education office of Pati Regency, from 2021 to today: 50 institutions, 2,000+ users and spreadsheets that never quite agreed. He turned them into one verifiable source of truth, and cut processing time by half with automated validation across 30 units.

Since 2026 he has also designed and built every system on this page for clients, and maintains pipeline-lint as an open source project. His rule is simple: when a pipeline breaks at 2 a.m., it should either fix itself or tell someone.

  1. 2026 to nowFounder and data engineer, Nafiul Data
  2. 2021 to nowData operations specialist, Dinas Pendidikan Kab. Pati
  3. 2018Web systems developer intern, PDAM Tirta Bening Kab. Pati
  4. 2015 to 2020Bachelor’s in Information Engineering, Universitas PGRI Semarang

Databricks Fundamentals Accreditation (2026). HackerRank certified in Python (Basic), SQL (Intermediate) and REST API (Intermediate).

LinkedIn

Nafiul is also open to remote Data Engineer roles. Recruiters are welcome to get in touch.

Tell us what your data looks like today.

Messy spreadsheets, a warehouse nobody trusts or a pipeline that fails quietly at night. Send a short note about where it hurts and we’ll suggest a first step.

nafiulhadisaputraa@gmail.com